Beyond blockHeight and Protobuf: Instant Settlement, Deterministic CBOR, and Serverless Edge Ledgers
Software engineering has a habit of turning temporary compromises into permanent assumptions. A decision made to accommodate early hardware or a particular workload can become an unquestioned law a decade later.
In blockchain architecture, three assumptions stand out:
- A blockchain must produce blocks at fixed intervals, and every contract must use
blockHeightas its clock. - A binary protocol should use Google Protobuf, even if consistent hashing requires nested serialization through
google.protobuf.Anyand the frontend must ship megabytes of generated code. - Running a chain requires an always-on cloud server hosting a full node, even when no transactions arrive at three in the morning.
As we rebuilt @ocap/ledger-core for thousands of ARCs (Agentic Realm Computers) and enterprise sovereign ledgers, we reconsidered all three.
We removed blockHeight and the public transaction queue in favor of per-transaction instant settlement, removing the public-mempool waiting window used for sandwich attacks. We replaced Protobuf in the transaction wire format with RFC 8949 Deterministic CBOR, reducing the client SDK's encoding footprint by 1.34 MB, or 99.4%. And we enabled a complete verifiable ledger to run on Cloudflare Workers + Durable Objects SQLite + R2, with compute that can scale to zero while idle.
1. Replacing blockHeight and the mempool with instant settlement
Why did Satoshi Nakamoto group Bitcoin transactions into roughly ten-minute blocks in 2008?
In a permissionless proof-of-work (PoW) network, miners around the world needed a sufficiently long interval to limit forks and amortize network propagation delays. Ethereum later shortened the interval to 12 seconds, and high-performance chains brought it down to hundreds of milliseconds. Yet the underlying pattern persisted: transactions wait in a public mempool, enter a periodically produced block, and use blockHeight to drive state-machine deadlines.
That pattern creates two engineering problems.
Public mempools expose pending transactions to sandwich attacks
Even a 200-millisecond stay in a public mempool can expose a transaction's slippage tolerance to automated attackers. They can compete to place one transaction ahead of it and another behind it, manipulating execution around the user's request. Flashbots-style private submission channels, encrypted mempools, and dedicated MEV auction layers address this exposure, but they add machinery around a waiting window created by the architecture itself.
blockHeight is a poor clock
Using blockHeight for stake-release periods, Dutch-auction decay, or auction deadlines is awkward. Congestion or a change in block-production rate can shift a nominal seven-day release period. An edge ledger that scales to zero has an additional problem: when there are no transactions, it should not generate empty blocks every second merely to advance blockHeight.
Streaming sequence assignment and timestamp-based state machines
In @ocap/ledger-core, we removed the public mempool and state dependencies on blockHeight, establishing blockless, streaming 100% Instant Settle:
- Sequence on arrival, settle on execution. Once an admitted transaction enters the sequencing channel, it immediately receives a monotonically increasing global
ledgerSequenceand a deterministictxTimestampSeconds. The engine executes the state transition, updates the incremental Merkle state tree (SMT), and returns a receipt with a cryptographic inclusion proof within milliseconds. - Remove the public-mempool sandwich window. Transactions settle atomically in
FIFOorder as they enter the sequencing channel. There is no public queue of pending transactions for a block builder to inspect and reorder around a target transaction. - Use pure timestamp state machines. Every time-dependent protocol primitive is a pure function of
(txTimestampSeconds, onChainState). This includes stake-revocation deadlines (revokingUnlockAt), linear decay in Dutch auctions, English-auction extensions (antiSnipeWindowSeconds = 300s), and delegation-expiry checks. None implicitly depends onblockHeight.
2. Why Deterministic CBOR replaces Protobuf
Once sequencing is settled, another foundational question remains: which binary representation should a transaction use for transmission and cryptographic signing?
Earlier ArcBlock chains used Google's Protocol Buffers (Protobuf), as do many other systems, including Cosmos SDK chains. Protobuf works well for microservice RPC. For blockchain transactions that require identical cryptographic hashes across implementations, however, we encountered three problems.
Protobuf serialization is not inherently canonical
Signature verification requires the same logical data to produce exactly the same bytes across languages and platforms. Different bytes produce different SHA-256 hashes and invalidate the signature.
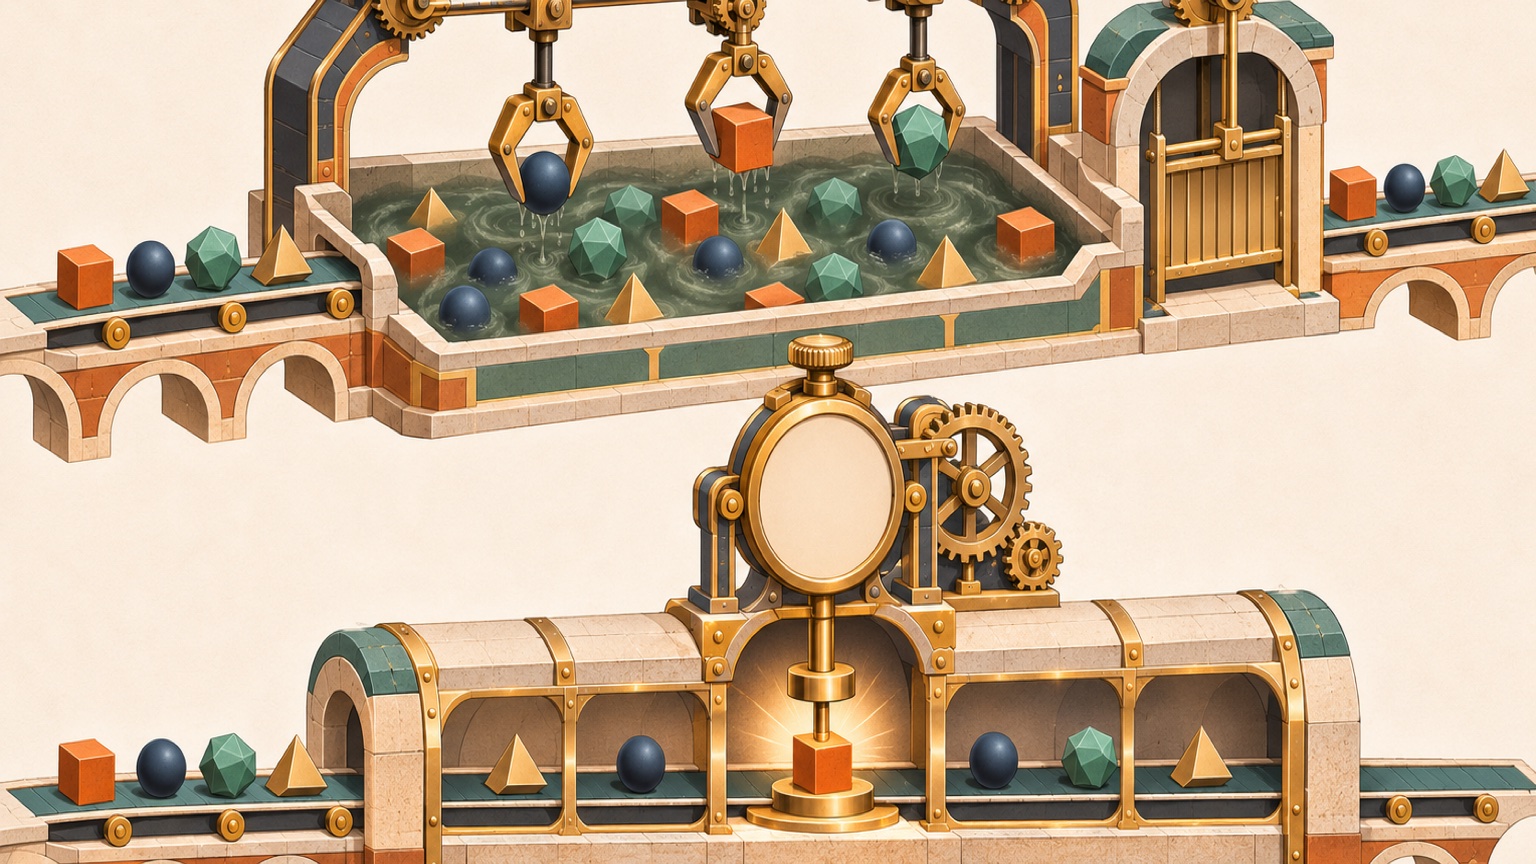
Standard Protobuf serialization does not guarantee identical output across implementations. Map ordering, unknown-field handling, and default-value encoding can differ. The legacy protocol worked around this by first serializing the inner transaction payload itx into bytes, placing those bytes in google.protobuf.Any.value, and wrapping the result in an outer Transaction Protobuf message. This nested serialization made debugging harder and added wire-format and parsing overhead.
A 1.35 MB frontend dependency
Size was especially painful for browser, mobile, and lightweight AI agent clients. Constructing and signing a transaction in a browser wallet or WeChat mini program required the google-protobuf runtime and tens of thousands of lines of generated schema code: 1.35 MB uncompressed.
A full migration to RFC 8949 Deterministic CBOR
We completed a five-stage wire-format migration in ArcBlock/blockchain, moving transaction encoding, signing domains, and storage snapshots to the IETF standard RFC 8949 Deterministic CBOR (Concise Binary Object Representation):
- Self-described CBOR tag
55799(0xD9 D9F7). Each encoded transaction carries the standard self-description header, allowing a parser to recognize CBOR without relying on external API context. - Ordered integer keys and an inline
itxmap. Existing numeric field identifiers become integer CBOR map keys, with strict ascending byte order enforced by the encoder. The inneritxis embedded directly as a child map, removing the extra serialization throughgoogle.protobuf.Any. - Native byte strings and arbitrary-precision integers. Addresses, public keys, and signatures use native
bstrvalues rather than repeated Base58 or hex conversion. Token amounts use CBOR's standardTag 2 / Tag 3bignums to preserve precision across languages.
The resulting differences are concrete:
| Dimension | Legacy Protobuf + Any | Deterministic CBOR (RFC 8949) | Result |
|---|---|---|---|
| Cryptographic determinism | Nested serialization in Any.value works around nondeterminism | Bit-for-bit deterministic encoding at the protocol layer | Direct hashing and signature verification without a second wrapper |
| Client encoding dependencies | google-protobuf + generated code ≈ 1,350 KB | Minimal deterministic cborg wrapper ≈ 8 KB | 1.34 MB smaller (-99.4%) |
| Standard transfer wire size | 213 Bytes | 196 Bytes | Wire size change: -8.0% |
| Light-node and hardware parsing | Large .proto descriptor tables must be loaded | Self-describing streaming parsing without a schema | Suited to hardware clear signing and microkernels |
3. A serverless edge ledger on Durable Objects and R2
A roughly 100 KB verifiable ledger core (@ocap/ledger-core), blockless instant settlement, and an 8 KB Deterministic CBOR codec make a different deployment model practical:
An application chain or sovereign ledger can run directly at the serverless edge, without a dedicated, always-on Linux VM.
With the lightweight core validated for Cloudflare Workers and Durable Objects compatibility, we designed two edge deployment topologies for different ledger scales.
Sovereign ledgers and dedicated ARC chains: SQLite hot state, R2 cold history
For enterprise sovereign ledgers, large community chains, and high-concurrency ARC instances, we use Cloudflare Workers + Durable Objects (DO) SQLite + R2 object storage as a tiered serverless engine:
- A single-threaded, strongly consistent sequencer. In Verifiable Single Sequencers and Multi-Validator BFT, we discussed why a lock-free, single-threaded state machine operating on memory or local state is so fast. A Durable Object provides a globally unique, single-threaded actor. One DO instance can serve as an
Instant Settledeterministic sequencer without an external distributed lock. - Up to 10 GB of hot SQLite state, with cold segment bundles in R2. Active account state trees (SMT) and recent transaction indexes remain in the DO's low-latency SQLite store. An asynchronous background pipeline packages sealed history segments and Merkle proof bundles into tamper-evident
Segment Bundlesand archives them in Cloudflare R2, which has no egress charges. - WebSocket hibernation and scale to zero. With the Hibernatable WebSockets API, thousands of wallets can retain event subscriptions while an idle compute instance hibernates. When the next transaction reaches the edge gateway, the instance wakes, sequences the transaction, persists it, and broadcasts the receipt within milliseconds.
An edge shield for the public main chain
For the public main chain, which handles settlement among independent parties and high transaction concurrency, the multi-node HotStuff-Lite cluster runs on dedicated high-performance nodes. Cloudflare Workers and R2 form a global edge shield in front of that cluster.
The edge layer rejects malicious traffic and checks transaction signature formats close to users. Historical block queries, Merkle inclusion proofs, and BitstringStatusList bitmaps are cached through edge R2 and KV. Most read-only queries and light-node verification requests can therefore be answered at the edge, leaving the core sequencing and consensus nodes to execute state transitions.
Good architecture removes unnecessary machinery
These three changes follow the same engineering principle: revisit the underlying requirement and remove intermediate layers that no longer serve it.
- A single sequencer and incremental state tree can produce a mathematically verifiable receipt within milliseconds. We removed the public mempool and
blockHeightpolling, gaining100% Instant Settleand removing the public queue used for sandwich reordering. - A ledger requires identical bytes across languages. We removed the 1.35 MB Protobuf runtime and nested
Anyserialization, replacing them with 8 KB of RFC 8949 Deterministic CBOR tooling. - A small, self-contained kernel with separate hot and cold storage can run on demand. We removed always-on idle servers, allowing verifiable ledgers to wake for work and scale compute to zero between requests.